GPU Clusters
Interconnected multi-GPU servers designed to run as a single resource for parallel training, simulation and rendering.
Scale-up and scale-out
Inside a server, GPUs communicate over NVLink/NVSwitch or Infinity Fabric (scale-up) or over PCIe. Between servers, traffic crosses the network fabric (scale-out) — InfiniBand or RDMA-capable Ethernet. Collective operations such as all-reduce are bounded by the slowest link in that path, so the fabric is sized from the gradient or activation traffic of the workload.
GPU memory does not simply add up
Eight 80 GB GPUs do not behave as one 640 GB device. A model larger than one GPU's memory has to be split using tensor, pipeline or fully-sharded data parallelism, and each method adds communication and per-GPU overhead. The GPU VRAM calculator shows per-GPU memory under these parallelism settings.
Facility checks
Dense GPU servers commonly draw multiple kilowatts each. Check rack power per phase, PDU capacity, cooling capacity per rack and floor loading before committing to a cluster layout — the rack power and cooling calculators do this arithmetic.
9 products
Compare selected
Supermicro
Supermicro 8U GPU SuperServer (SYS-821GE-TNHR)
- GPU count
- 8
- GPU model
- NVIDIA HGX GPU Baseboard 8 H200 141GB
- CPU model
- Dual 5th/4th Gen Intel Xeon Scalable Processors
₹5,12,07,811
Built to order
Supermicro
Supermicro 8U GPU SuperServer (SYS-822GS-NB3RT)
- GPU count
- 8
- GPU model
- 8 Onboard NVIDIA HGX B300 GPUs
- CPU model
- Dual Intel Xeon 6700 Series Processors with P-cores
₹9,03,53,780
Built to order
NVIDIA
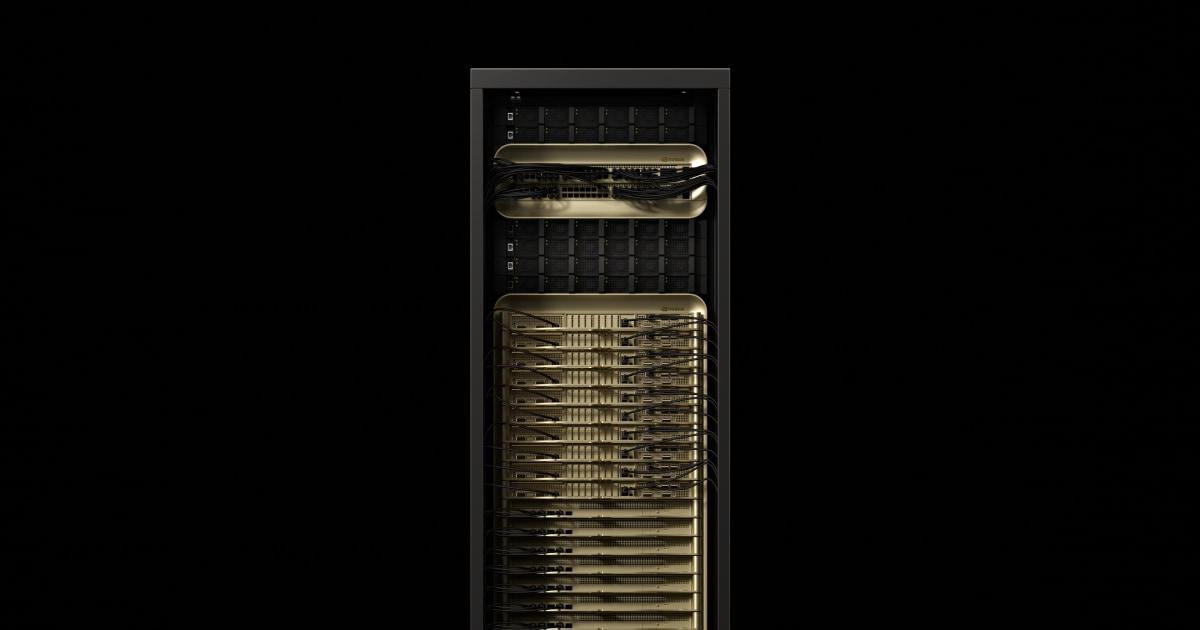
NVIDIA GB300 NVL72 Rack-Scale AI Factory
- GPU count
- 72
- GPU model
- 72 NVIDIA Blackwell Ultra GPUs, 36 NVIDIA Grace CPUs
- Total GPU memory
- 20,000 GB
₹71,86,20,000
Built to order
Supermicro
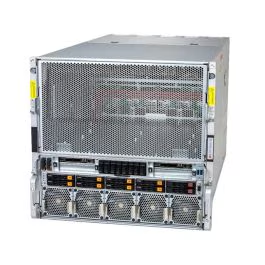
Supermicro 10U GPU SuperServer (AS -A126GS-TNBR)
- GPU count
- 8
- GPU model
- 8 Onboard NVIDIA HGX B200 GPUs
- CPU model
- Dual AMD EPYC 9005/9004 Series Processors
₹7,26,70,572
Built to order
NVIDIA
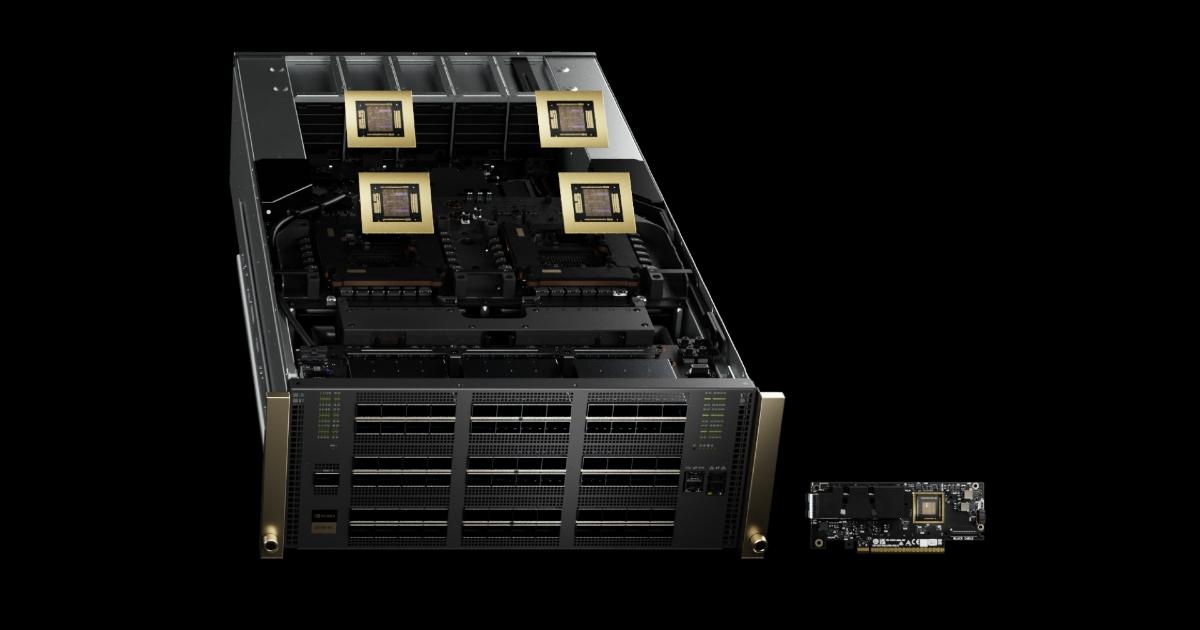
NVIDIA Quantum-X800 Q3400-RA InfiniBand XDR Switch (144 × 800 Gb/s, 4U)
- Network speed
- 800 Gb/s
₹1,71,10,210
Built to order
Specifications to compare
- GPU count
- Memory per GPU
- Total GPU memory
- Interconnect
- Network speed
- Max system power