AI Inference
Serving trained models to users and applications with predictable latency.
What matters, in order
- Memory for weights and KV cache
- Memory bandwidth (token generation speed)
- Throughput per watt and per rupee
- Batching and concurrency
Engineering guidance
Token generation is usually memory-bandwidth bound: each generated token reads the model weights once per batch step. Quantisation (FP8, INT8, INT4) reduces memory and increases tokens per second at some accuracy cost; the KV cache grows with context length and concurrent users.
Products tagged for AI Inference
28 products
Compare selected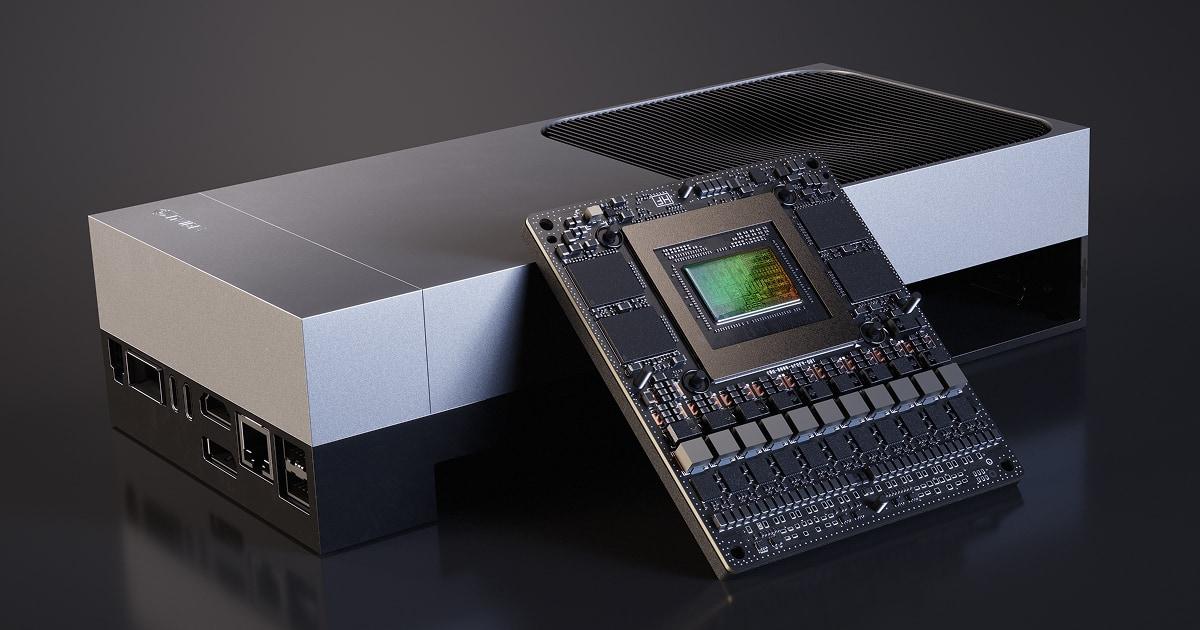
NVIDIA
NVIDIA Jetson AGX Thor Developer Kit
- GPU model
- 2,560-core NVIDIA Blackwell GPU, fifth-gen Tensor Cores, MIG with 10 TPCs
₹8,78,524
Backorder
Corsair
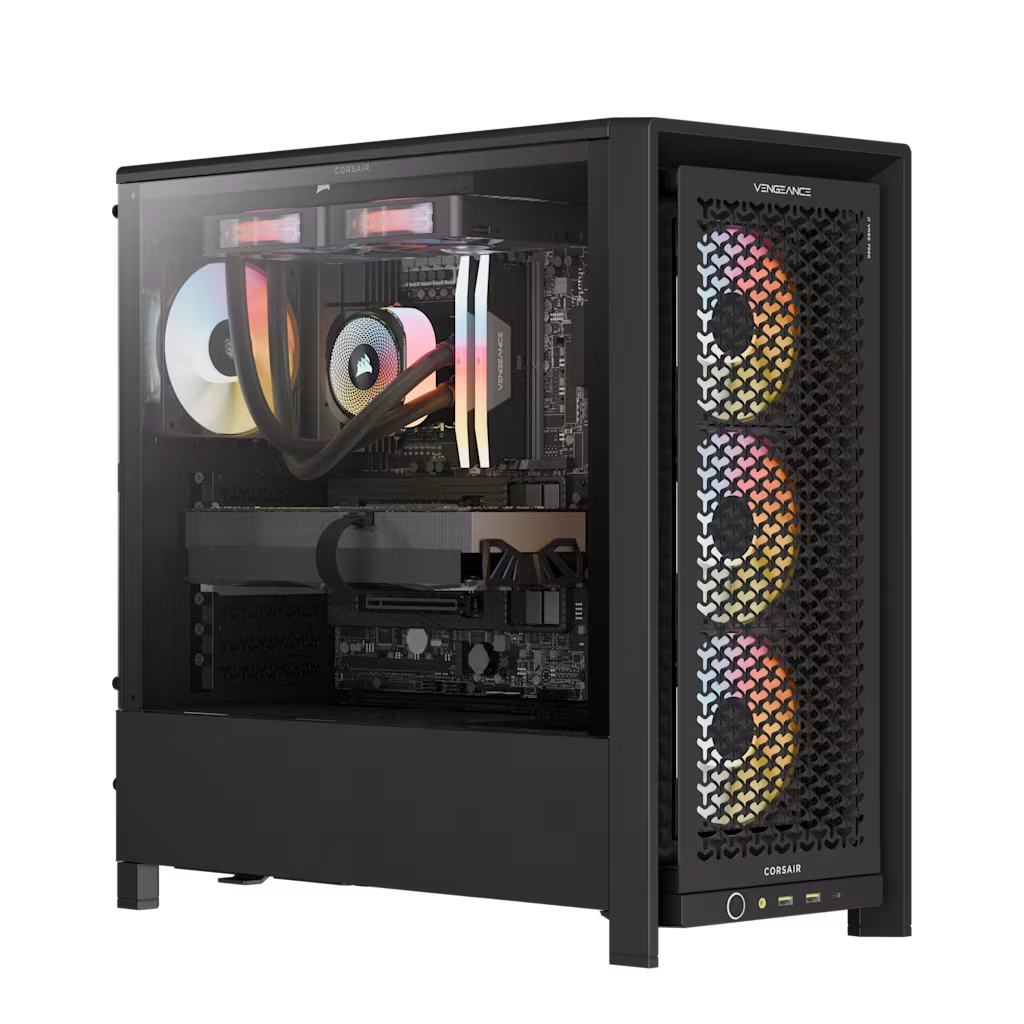
CORSAIR VENGEANCE a7500 AIR Gaming PC — Ryzen 9 9950X3D, GeForce RTX 5090, 64GB DDR5, 4TB
- GPU model
- NVIDIA GeForce RTX 5090
- CPU model
- AMD Ryzen 9 9950X3D
- Memory
- 64 GB
₹18,21,270
Backorder
Apple
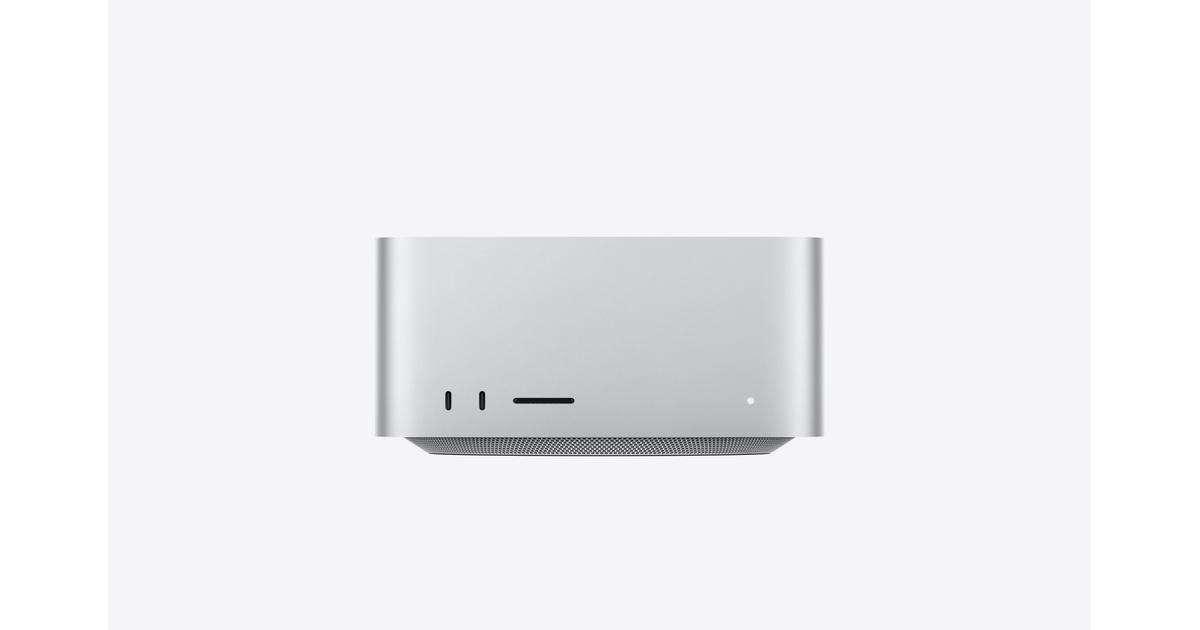
Apple Mac Studio (M5 Ultra)
- GPU model
- 64-core GPU (80-core available)
- CPU cores (total)
- 30
- CPU model
- Apple M5 Ultra
₹6,29,900
Backorder
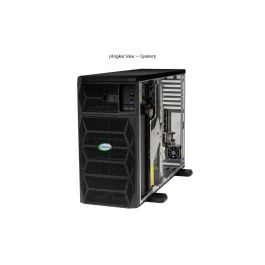
Supermicro
Supermicro Liquid Cooled GPU Super AI Station (ARS-511GD-NB-LCC)
- GPU count
- 1
- GPU model
- 1 Onboard NVIDIA Blackwell Ultra GPU, 252GB GPU HBM3e Memory
- CPU model
- NVIDIA 72-core NVIDIA Grace CPU on NVIDIA GB300 Grace Blackwell Ultra Desktop Superchip
₹1,61,15,171
Built to order
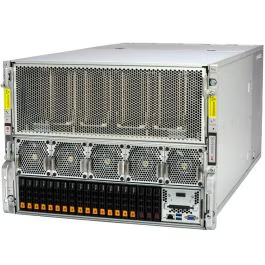
Supermicro
Supermicro 8U GPU SuperServer (SYS-821GE-TNHR)
- GPU count
- 8
- GPU model
- NVIDIA HGX GPU Baseboard 8 H200 141GB
- CPU model
- Dual 5th/4th Gen Intel Xeon Scalable Processors
₹5,12,07,811
Built to order
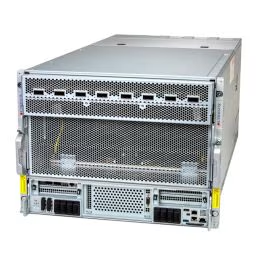
Supermicro
Supermicro 8U GPU SuperServer (SYS-822GS-NB3RT)
- GPU count
- 8
- GPU model
- 8 Onboard NVIDIA HGX B300 GPUs
- CPU model
- Dual Intel Xeon 6700 Series Processors with P-cores
₹9,03,53,780
Built to order
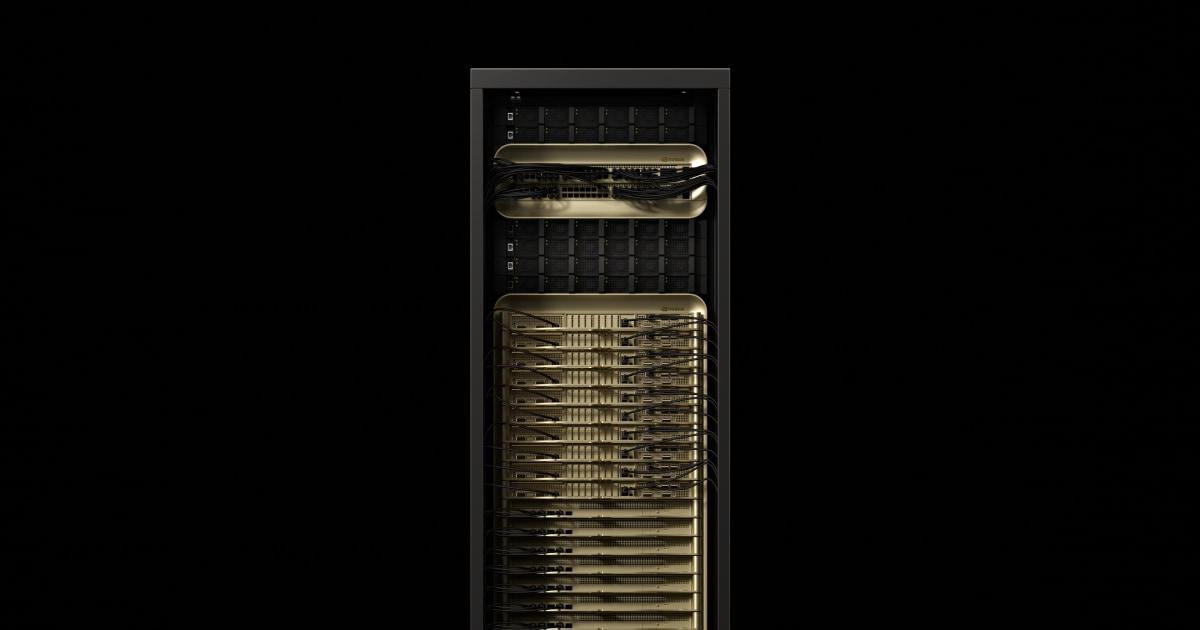
NVIDIA
NVIDIA GB300 NVL72 Rack-Scale AI Factory
- GPU count
- 72
- GPU model
- 72 NVIDIA Blackwell Ultra GPUs, 36 NVIDIA Grace CPUs
- Total GPU memory
- 20,000 GB
₹71,86,20,000
Built to order
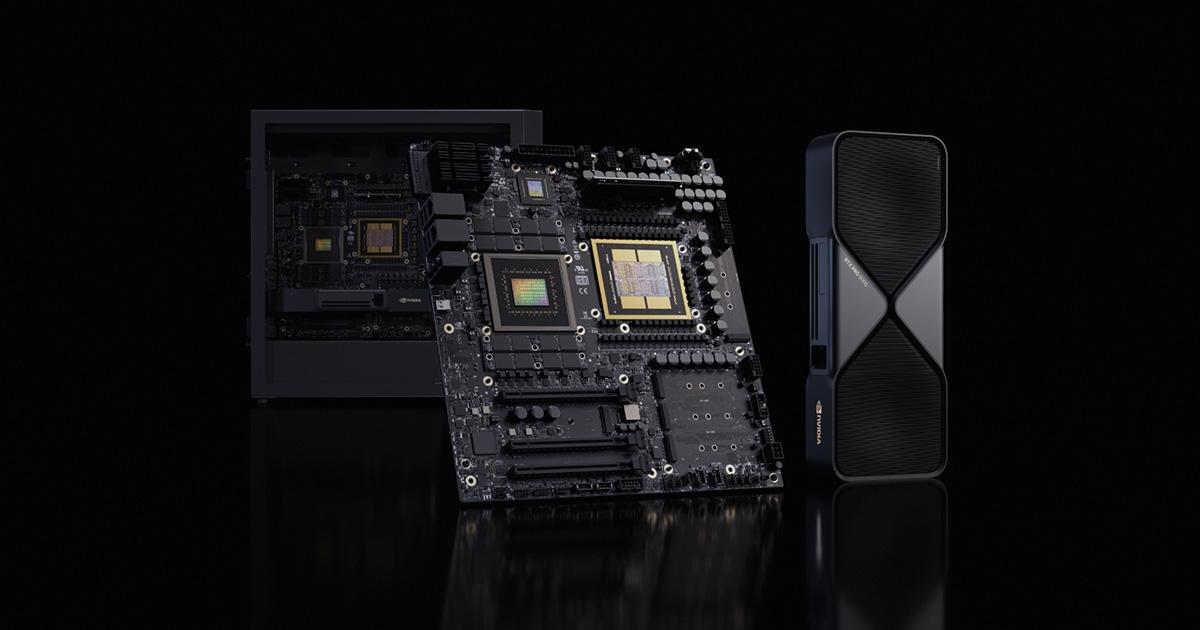
NVIDIA
NVIDIA DGX Station (GB300 Grace Blackwell Ultra)
- GPU count
- 1
- GPU model
- 1x NVIDIA Blackwell Ultra
- Memory per GPU
- 252 GB
₹1,67,47,713
Built to order
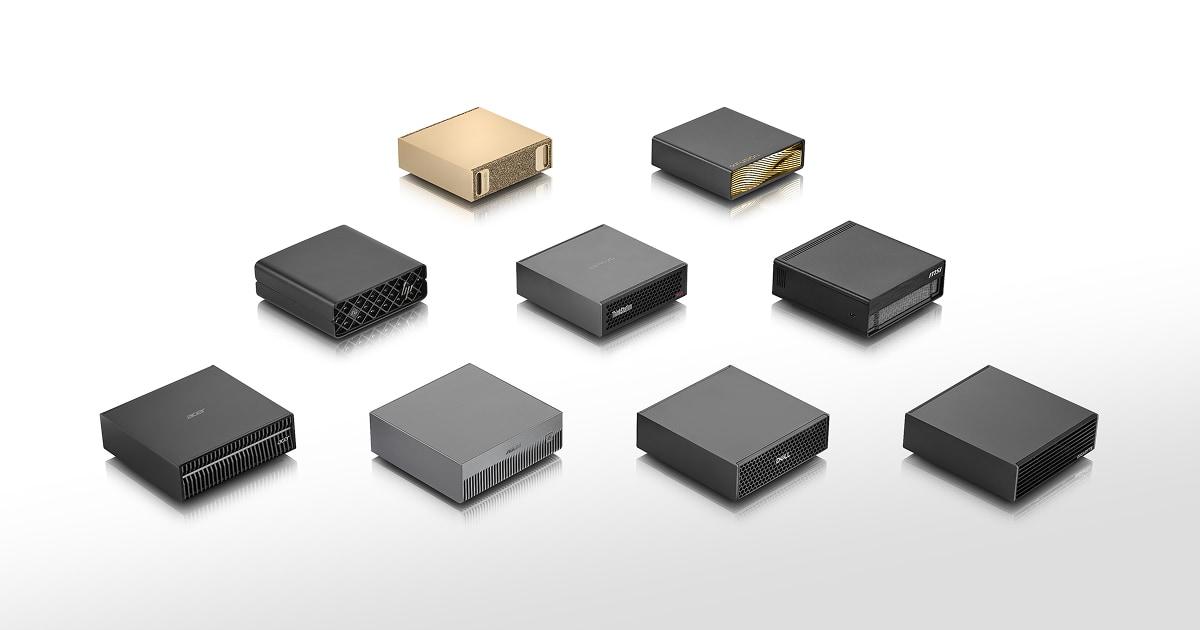
NVIDIA
NVIDIA DGX Spark Personal AI Supercomputer (128 GB, 4 TB)
- GPU model
- NVIDIA GB10 Grace Blackwell Superchip
- Memory
- 128 GB
- Storage capacity
- 4 TB
₹11,10,337
Backorder
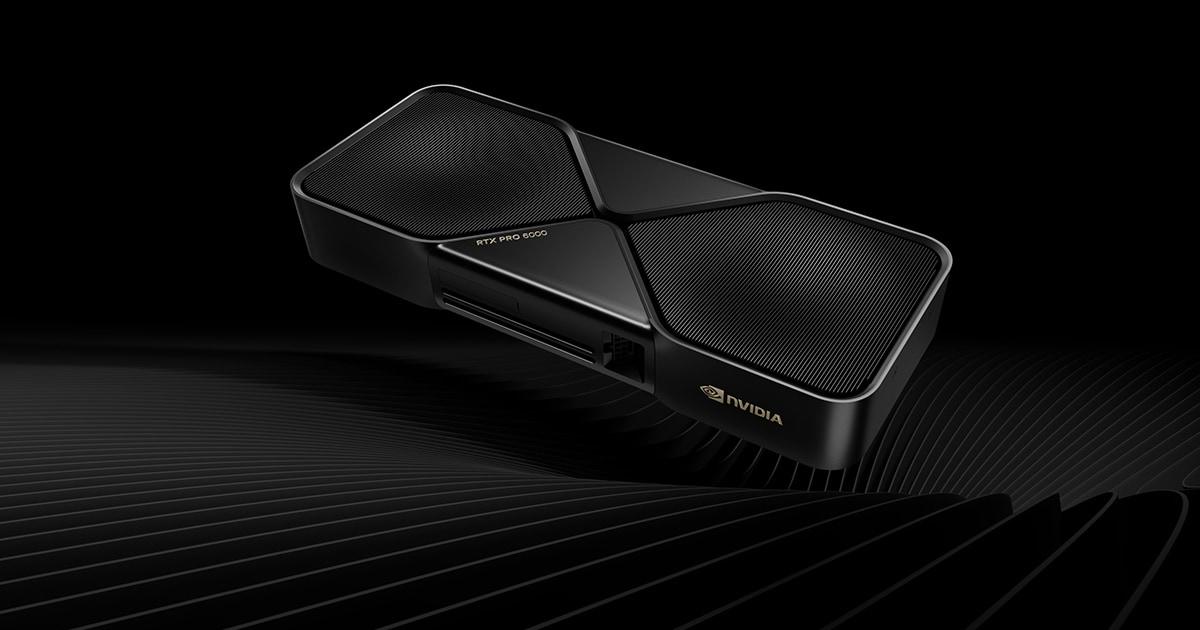
NVIDIA
NVIDIA RTX PRO 6000 Blackwell Workstation Edition
- GPU model
- RTX PRO 6000 Blackwell
- Memory per GPU
- 96 GB
- Form factor
- 5.4" H × 12.0" L, dual slot
₹25,56,171
Backorder
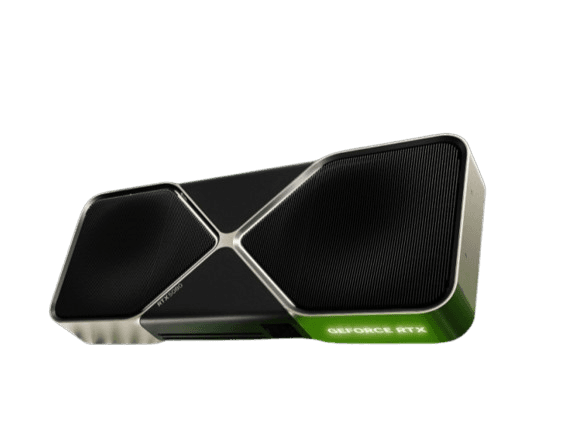
NVIDIA
NVIDIA GeForce RTX 5080 Founders Edition
- GPU model
- GeForce RTX 5080 (Blackwell)
- Memory per GPU
- 16 GB
₹1,72,550
Backorder
NVIDIA
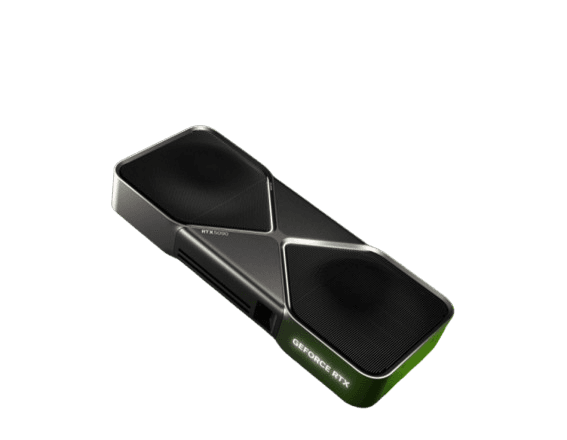
NVIDIA GeForce RTX 5090 Founders Edition
- GPU model
- GeForce RTX 5090 (Blackwell)
- Memory per GPU
- 32 GB
₹3,91,500
Backorder
GIRIVON
Private Cloud Platform Engineer — Kubernetes, OpenStack & virtualisation (per day)
₹2,50,000
Built to order
NVIDIA
NVIDIA H100 PCIe 80GB Tensor Core GPU
- GPU model
- NVIDIA H100 (Hopper)
- Memory per GPU
- 80 GB
₹43,60,732
Backorder
Supermicro
Supermicro IOT/Embedded System (AS -E300-14GR)
- CPU model
- Single AMD EPYC 4005/4004 & Ryzen Series Processors
- Form factor
- Mini-1U
₹6,87,238
Built to order
Supermicro
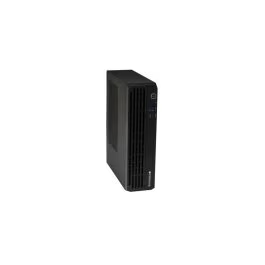
Supermicro AI PC A+ Slim Tower (AS -C521D-11302U)
- CPU model
- Single AMD Ryzen 9700X Processor (8-Cores)
- Form factor
- Slim Tower
₹3,37,156
Built to order
Supermicro
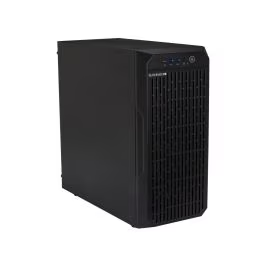
Supermicro Mid-Tower Mainstream Client System (SYS-C542i-11302U)
- CPU model
- Intel Core Ultra 7 265 Processor (20 Cores)
- Form factor
- Mid-Tower
₹2,83,570
Built to order