Supermicro
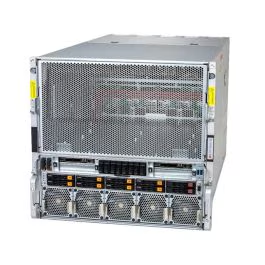
Supermicro 10U GPU SuperServer (AS -A126GS-TNBR)
- GPU count
- 8
- GPU model
- 8 Onboard NVIDIA HGX B200 GPUs
- CPU model
- Dual AMD EPYC 9005/9004 Series Processors
₹7,26,70,572
Built to order
Training and pre-training neural networks across one or many accelerators.
Training compute is roughly 6 × parameters × tokens floating-point operations. Mixed-precision Adam needs about 16 bytes of accelerator memory per parameter for weights, gradients and optimizer states before activations, so large models are sharded across GPUs with fast interconnects.
27 products
Compare selectedSupermicro
₹7,26,70,572
Built to order
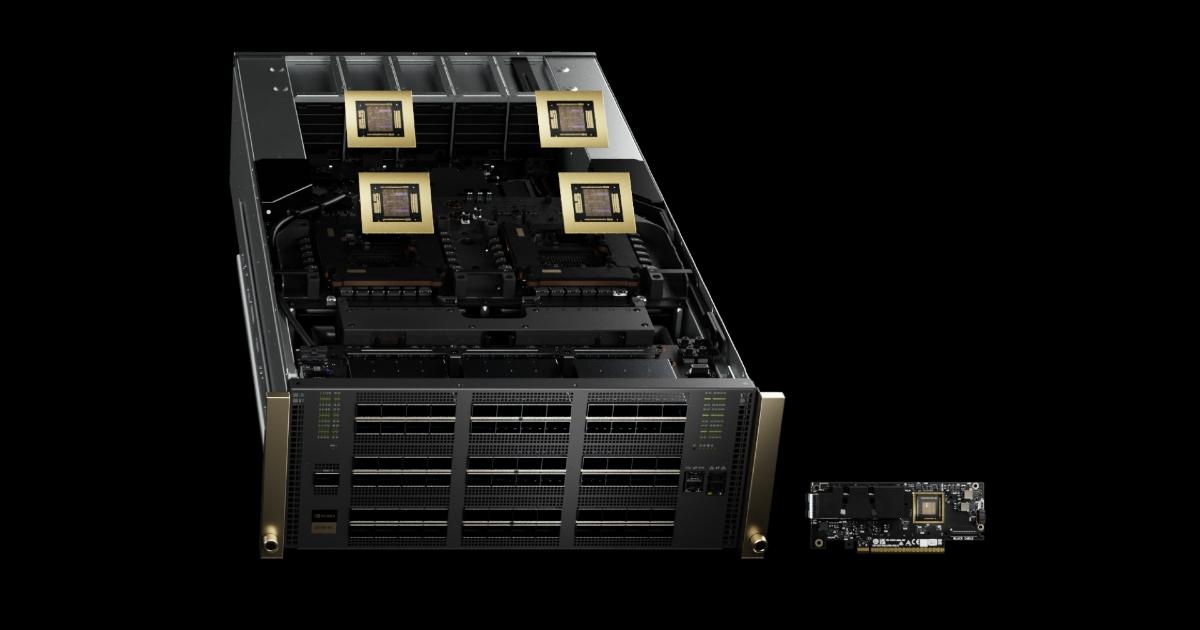
NVIDIA
₹1,71,10,210
Built to order
NVIDIA
₹9,38,818
Backorder